client work
Digital Democracy Project
A containerized, asynchronous civic-data pipeline that reconciles legislative records with constituent participation, turns them into reusable accountability scorecards, and publishes reliable data products across APIs, static clients, and CMS workflows. Recent production hardening replaced fragile CMS synchronization with stable-key, update-only, self-healing behavior validated against live data.
visit project ↗the project
Digital Democracy Project is a non-partisan civic-data platform that polls registered voters about specific legislation, maps the results by legislative district, and compares constituent sentiment with representatives' recorded votes.
There are two theses behind the project. First, once you remove party identity and political personalities and ask people about specific issues, I suspect we agree more often than our political discourse would suggest. By mapping those opinions locally, we can test that idea with data and see where our neighbors actually agree and disagree.
Second, representative government should provide some meaningful connection between the preferences of constituents and the decisions made by their elected representatives. Digital Democracy Project makes one part of that relationship measurable: for each piece of legislation we track, we compare how registered voters in a district say they want their representative to vote with how that representative actually voted.
The result is a scorecard showing the legislation we've tracked, constituent opinion on each bill, the representative's recorded vote, and the degree of alignment between the two. It doesn't attempt to explain why a representative voted a particular way; it makes the underlying constituent and voting data visible so people can evaluate that relationship for themselves.
The project's scope and capabilities are expanding quickly, so this case study may already be out of date.
Digital Democracy Project began as a much smaller application supporting only Florida. I originally built it in PHP and MariaDB, with much of the data model and business logic implemented in SQL stored procedures and a fairly rough PHP application handling data retrieval and ETL. It worked, and it let us prove the concept quickly, but I had optimized for getting the idea working rather than for what the application might eventually become.
As the project expanded beyond Florida, the cracks started to show. Supporting multiple states introduced substantially more data and complexity, while new requirements such as ranked-choice polling no longer fit comfortably into the original model. Business logic had become distributed between PHP and an increasingly complicated collection of stored procedures, making the application difficult to reason about, test, and extend. Performance was also becoming unacceptable. The prototype had done its job; it was time to rebuild the application around what the project had become.
the system
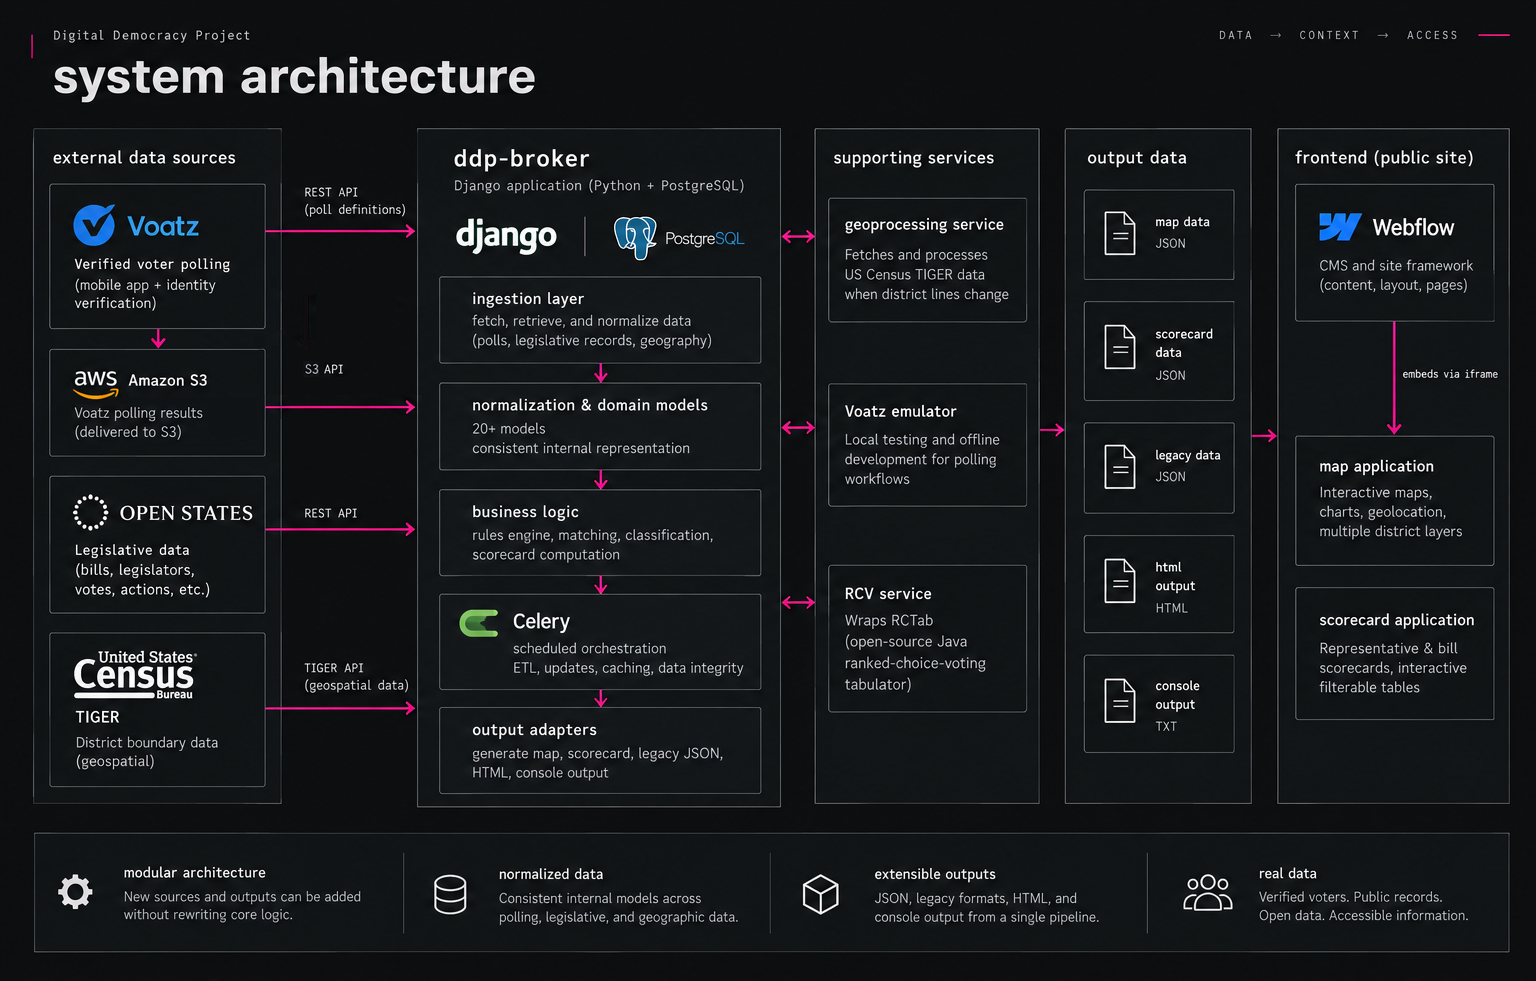
Our data sources include Voatz, a blockchain-based mobile election platform that performs identity verification against voter registration records; Open States, which collects and normalizes legislative data from government sources; Amazon S3, where polling results from Voatz are delivered; and Webflow, which provides content managed by the project team. Voatz's role is particularly important: poll participants are verified as registered voters before participating, rather than being anonymous respondents to an internet poll. Open States provides normalized legislative information including bills, legislators, actions, and votes across jurisdictions.
I rebuilt the backend using Python, Django, and PostgreSQL. The current application has a 20+ model domain architecture and more than 10,000 lines of Python covering ingestion, normalization, business rules, and data delivery.
Because legislative data isn't always as clean or consistent as we'd like, I built a custom rules engine that classifies bill motions and resolves ambiguous legislator matches in data received from Open States. Rather than baking each external system directly into the application, I built modular interfaces around both ingestion and output: new data sources can be added without refactoring the ingestion pipeline, while output adapters let us create new delivery formats without recreating ETL logic.
I also introduced a QueryFilter abstraction for dynamically defining subsets of the domain data. A scorecard, for example, can be limited to a particular collection of bills, a legislative session, or another dynamically defined set without requiring special-purpose query logic for each use case.
Several applications work in concert to power what we've dubbed ddp-broker. The broker itself is a Django application responsible for orchestration, ETL, normalization, caching, business rules, and data delivery. Supporting services include a geoprocessing application that automatically retrieves updated district boundaries from the U.S. Census TIGER service when district lines change; a Voatz emulator that allows us to test polling workflows and develop offline without relying on the production service; and a ranked-choice-voting service that wraps RCTab, an open-source Java application designed specifically for tabulating RCV elections.
A scheduled Celery task retrieves the Voatz polls representing legislation we're currently tracking. Those polls are matched with polling results delivered through S3, and the resulting bill and polling data is normalized and stored in PostgreSQL.
A separate ingestion pipeline retrieves legislative data from the Open States REST API for those bills, including legislators, actions, and recorded votes. This is where the rules engine does a lot of its work: legislative data is surprisingly messy, particularly when trying to normalize information originating from dozens of state legislative systems. Open States does an enormous amount of the hard work required to make this possible in the first place, so huge props to their volunteers.
Once normalized into the application's domain model, data can be retrieved through output adapters that transform it into the schemas used by our maps and scorecards. The current implementation produces .json files in a filesystem structure accessible to the frontend applications. That's deliberately an intermediate step: the same adapter architecture is intended to sit behind a full API incorporating the QueryFilter system.
The public site itself uses Webflow as its CMS and presentation framework, with two separate JavaScript applications embedded into it. The map application provides interactive charts, geographic navigation and geolocation, and supports multiple legislative-district boundary layers. The scorecard application consumes the generated .json datasets and turns them into interactive, filterable tables comparing constituent polling results with legislators' recorded votes.
supporting work
Legislative data is messy. Open States does an enormous amount of work to normalize information from state legislatures, but ambiguities inevitably remain. I built a rules engine to classify legislative motions and resolve ambiguous legislator matches using application-specific rules, turning inconsistent source records into predictable domain objects without scattering special cases throughout the ETL code.
After implementing the original scorecards in PHP, I knew the new system needed to be considerably more flexible. I built a single scorecard computation pipeline that produces a typed internal representation, which adapters transform into current JSON, legacy JSON, HTML, and developer-facing console output. Adding a new consumer doesn't require rewriting the underlying policy logic, while the typed schemas give frontend and legacy consumers a stable interface even as the broker's internal models evolve.
decisions and current state
Polling data, legislative records, and district geography come from entirely different sources and don't share a clean vocabulary—or even necessarily agree about the things they describe. Keeping normalization in explicit application models made those relationships much easier to inspect, test, and change than they had been in the stored-procedure-heavy legacy architecture.
As our ecosystem matured, security became an unexpected development constraint. Access to Voatz is tightly restricted, and after opening several tickets to regain access while I was traveling, I directed my frustration into building a Voatz emulator that lets me quickly reproduce polling scenarios and develop and test the broker without access to the production service. See XKCD #1205—in this case, "It Was Worth The Time"!
The resulting platform powers district-level polling maps and representative and bill scorecards, with a reusable pipeline for turning disparate polling, legislative, geographic, and representative data into consistent public-facing datasets. More importantly, the architecture gives us somewhere to go: new sources, output formats, jurisdictions, and frontend applications can be added without rebuilding the underlying data pipeline.
The project is still very much alive. Our future state includes expanding coverage to all 50 state legislatures and substantially more legislation, using LLMs trained for the domain to assist with summarization and data-integrity workflows, exposing scorecard, bill, representative, and legislative data through a full-featured queryable API, and replacing Webflow with a Django-based frontend built directly around the platform.